







Blogs
Explore insights, tips, and industry trends

Case studies
See how organizations achieve real results

eBooks and reports
Access in-depth research and expert analysis

Research
Discover original research and data-driven insights

Webinars
Join live and on-demand sessions with experts

Whitepapers
Access research and expert analysis

Academy
Build skills with structured courses and training

Certified trainers
Get expert training from certified professionals

International partners
Connect with trusted partners around the world

Knowledge center
Find guides, tutorials, and product documentation




Thematic analysis of interview data: 6 ways NVivo AI Cloud can help
Key takeaways
Learn how to conduct a thematic analysis of interviews, step by step—and how NVivo’s AI Cloud can simplify and speed up your research.

Introduction
Interviews are a key method of collecting qualitative data—revealing how participants think, behave, and make sense of their experiences. Analyzing qualitative data from interviews requires a structured process that can handle open-ended responses while remaining flexible to patterns that emerge during review.
Thematic analysis is one of the most widely used approaches for identifying meaning in qualitative data. It involves coding transcripts and building meaningful themes that help explain what matters to participants. This approach works well with in-depth interviews, especially when your research objectives include describing shared experiences or exploring variation across responses.
While thematic analysis can be done manually, qualitative data analysis software (QDA software) like NVivo AI Cloud helps researchers stay organized, manage coding across multiple files, and track decisions throughout the process. AURA, NVivo AI Cloud’s AI-powered Unified Research Assistant, works throughout that process—identifying topics, suggesting codes, and answering questions grounded in your own project data. This article explains how conducting thematic analysis works for interview data, common challenges researchers face, and six specific ways NVivo AI Cloud supports each stage of the analysis.
The State of AI in Qualitative and Mixed Methods Research
Discover key findings on how researchers are adopting, trusting, and governing AI in their qualitative and mixed methods work.
Download report →What is interview data in qualitative research?
Interview data refers to the spoken responses collected during one-on-one or group interviews conducted as part of a research project. These interviews are typically semi-structured or open-ended, giving participants space to describe their thoughts, beliefs, or experiences in their own words. Researchers use interview data to understand individual perspectives on a topic, investigate how people make decisions, or trace how meaning is shaped through language.
The raw data usually takes the form of audio or video recordings, which are later transcribed into text for analysis. These transcripts often include not only what was said but also pauses, hesitations, or emphasis that may be relevant to interpretation. Depending on the research design, interviews may follow a consistent question guide across participants or adapt based on the conversation.
Unlike structured survey responses, interview data is unstructured and can vary widely in content and detail. A single interview may include personal stories, reflections, contradictions, or shifting viewpoints. This makes it rich in meaning but also challenging at times to analyze. Researchers often look for patterns, categories, or recurring phrases that help explain how participants understand the topic of interest.
Because interviews involve direct interaction, the role of the interviewer is also important. The wording of questions, tone, and follow-up prompts can all shape participants’ responses. Researchers must consider these dynamics when interpreting the results. For this reason, interview data is often used alongside other qualitative sources such as field notes, focus group transcripts, or open-ended survey responses.
In many studies, interviews are the primary source of the data because they provide detailed accounts that cannot be captured through standardized measures. This is particularly useful when studying new or sensitive topics, where participants’ own language and framing offer insights that might be missed with more rigid approaches. Whether conducted in person, online, or by phone, interviews remain a widely used method for generating qualitative data that is contextually grounded and participant-driven.lace. Buy NVivo today to get started.
Get the guide: The Interview-to-Insight Playbook for Qualitative Researchers
Learn how to conduct interview research with greater confidence and clarity—from study design to final insight.
Common methods of interview analysis
There are several ways to analyze interview data in qualitative research. The choice depends on the research question, the type of interview conducted, and the level of interpretation required. Some methods focus on developing theory, while others describe common patterns or examine how language is used.
Five commonly used approaches for analyzing interview data include:
- Grounded theory
- Narrative analysis
- Content analysis
- Discourse analysis
- Thematic analysis
Grounded theory
Grounded theory is an inductive method focused on developing theory from qualitative data rather than testing existing ideas. Researchers begin by coding data line by line and identifying concepts that emerge. These concepts are refined through constant comparison with other parts of the data. Over time, they are grouped into broader categories and linked to build a theoretical model.
The process includes open coding, memo writing, and theoretical sampling, where researchers collect data in additional iterations to develop and test emerging categories. Grounded theory is used when researchers want to explain processes, actions, or relationships rather than just describe them. This method works well with interview data that includes accounts of how people make decisions or respond to change over time.
Narrative analysis
Narrative analysis focuses on how participants construct stories about their experiences. Instead of breaking down the data into multiple codes and themes, this method treats the interview as a coherent account. Researchers examine structure, tone, and sequencing to understand how people make sense of events.
This approach is especially useful when participants describe personal journeys, life transitions, or critical incidents. Researchers may compare how different individuals tell similar stories or focus on a single narrative in depth. Narrative analysis is often used in psychology, health research, and education, where understanding lived experience is central.
Content analysis
Content analysis involves identifying the presence, frequency, or co-occurrence of specific words, phrases, or ideas in a dataset. It can be used to describe trends, compare responses, or quantify certain aspects of qualitative data. Researchers apply predefined or inductively developed codes and frequently count how often each of the same code appears.
While originally developed for analyzing media, content analysis is now widely used across fields. It is especially helpful when interview questions are highly structured or when comparing a large number of responses. This method works well with closed-ended questions followed by short explanations or when analyzing how often particular issues are mentioned.
Discourse analysis
Discourse analysis examines how language is used to construct meaning, identity, or power relations in a given context. Rather than focusing on what is said, it looks at how it is said and what that reveals about social norms or institutional structures.
Researchers using discourse analysis may focus on word choice, sentence structure, or rhetorical devices. They may also look at how participants position themselves and others during the interview. This method is common in sociolinguistics, critical studies, and education research. It is often applied when interviews are conducted on topics involving identity, inequality, or institutional discourse.
Thematic analysis
Thematic analysis is one of the most flexible and widely used methods for analyzing interview data. It involves identifying patterns of meaning, or themes, across a dataset. Researchers begin by coding meaningful segments of text and then group related codes into broader categories.
This method works well for describing how participants view a particular topic, especially when there are shared ideas or concerns across interviews. It can be applied inductively—letting the themes emerge from the data—or deductively, using a predefined framework. Inductive and deductive analysis represent only some of the possible types of thematic analysis, which may also differ in how structured the coding process is and how researcher interpretation is handled. Thematic analysis is used in psychology, health, education, and many other fields, and it supports both detailed description and interpretive analysis.
Unlike grounded theory, thematic analysis does not require theory development. And unlike content analysis, it does not involve counting or quantification. The focus is on meaning rather than frequency. Because of its flexibility and transparency, thematic analysis is often the method of choice for researchers working with interview transcripts, especially when using QDA software like NVivo to manage the process.
Challenges of thematic analysis of interview data
Thematic analysis is widely used because of its flexibility, but analyzing interview data with this method can present several challenges.
Some of the main challenges of conducting thematic analysis of interview data include:
- Managing large volumes of text
- Time-intensive transcription
- Inconsistent coding
- Difficulty moving from codes to themes
- Deciding which voices to prioritize
- Maintaining transparency without proper documentation or tools
One of the first challenges is managing large volumes of text. Interviews must be transcribed before analysis, which is time-consuming and can introduce errors if not done carefully. Even a small number of interviews can produce pages of transcripts, making it difficult to track patterns without a clear structure. Without tools to organize codes and memos, it’s easy to lose sight of earlier decisions or overlook recurring ideas.
Another challenge involves consistency in coding qualitative data. Because thematic analysis relies on interpreting meaning, researchers must decide what counts as a meaningful unit and how to apply codes across different interviews. These decisions can vary depending on the coder’s perspective or level of experience, especially when working in a team. Without a codebook or documentation of coding rules, it becomes difficult to maintain reliability across the dataset.
Researchers also face challenges when moving from codes to themes. Some codes may overlap, while others may not fit neatly into a broader category. It can be hard to know whether a theme is well supported by the data or if it reflects researcher assumptions. Reviewing and refining emerging themes takes time and requires going back to the data repeatedly.
Thematic analysis also involves decisions about which voices to highlight. If one participant describes an idea in detail while others mention it briefly, researchers must decide how to weigh each contribution. Similarly, patterns may emerge that reflect dominant viewpoints while marginal perspectives are overlooked. This can lead to findings that simplify or flatten complexity in the data.
Finally, documenting the process of thematic analysis can be a challenge. Without a clear record of coding choices, theme development, and revisions, it’s difficult for others to understand how the analysis was conducted. This affects transparency and can weaken the credibility of the findings. Using tools like NVivo AI Cloud that support memo writing, audit trails, and code organization can help manage common qualitative research challenges and improve the overall rigor of the analysis.
How to do a thematic analysis of interviews?
Thematic analysis can be applied systematically by following a series of steps that guide researchers from data familiarization to reporting. While the process may vary slightly depending on the study design, the following six steps provide a structure for working with interview data in a way that supports a qualitative data analysis that is rigorous and transparent.
The six steps of thematic analysis of interview data are:
- Familiarization with data
- Generating initial codes
- Search and develop themes
- Review themes
- Define and name themes
- Produce report
Step 1: Familiarization with data
The first step involves reading and re-reading the interview transcripts to become familiar with the content. If working from audio or video, this may include listening to the recordings during or after transcription. This stage is about getting a general sense of the topics covered, the language participants use, and any immediate patterns that stand out.
Researchers often make brief notes or memos during this stage to record early impressions. The goal is not to begin formal coding but to understand the depth and range of responses. This step helps identify areas of interest and lays the groundwork for later stages.
Step 2: Generating initial codes
Once familiar with the data, researchers begin assigning codes to segments of text. A code is a short label that captures the essence of what a participant is saying. For example, a participant’s comment about feeling frustrated with a process might be coded as “user frustration” or “barriers to access.”
Codes can be descriptive or interpretive. At this stage, researchers usually create many codes to capture different ideas, including contradictory or ambiguous statements. Coding is typically applied to short passages, though sometimes longer excerpts are grouped if they represent a single idea.
Codes can be developed inductively from the data or based on a prior framework. Either way, consistency matters. A codebook or list of definitions helps ensure that similar content is treated the same way throughout the dataset.
Step 3: Search and develop themes
After coding all transcripts, the researcher reviews the full list of codes and begins generating themes by grouping related codes together. A theme is a broader pattern that captures something meaningful about the data in relation to the research question. It may consist of several related codes or represent a recurring concept across interviews.
For example, codes such as “difficulty navigating system,” “lack of support,” and “confusing instructions” might be grouped under potential themes like “access challenges” or “negative experiences.” This stage involves sorting and comparing codes, looking for overlap, and identifying how codes relate to each other.
Visual aids such as tables, maps, or cluster diagrams may be helpful for organizing broad themes and identifying gaps or inconsistencies in how ideas are grouped.
Step 4: Review themes
Once preliminary themes are identified, the next step is to refine them by checking whether they accurately reflect the coded data and the overall dataset. Researchers revisit the coded excerpts and ask whether the theme is supported by enough evidence and whether it overlaps too much with another theme.
Some themes may need to be split, combined, or discarded. The review also includes checking how well separate themes work across different interviews. A strong theme should capture something relevant and repeated but also allow for variation in how it is expressed by participants.
This review process may require adjustments to the initial coding or revisions to theme definitions. It is often iterative, with researchers moving back and forth between codes, data, and themes until the structure feels coherent.
Step 5: Define and name themes
Once themes are finalized, they need to be clearly defined and named. Each theme should have a concise label and a short description that explains what it covers and how it relates to the research question.
This stage involves writing brief summaries of each theme, identifying key supporting quotes, and distinguishing one theme from another. The naming of themes should be specific enough to guide interpretation but broad enough to capture variation in the data.
If subthemes are used, they should be nested logically within larger themes. Defining themes in writing helps prepare for the final reporting stage and supports transparency in how decisions were made.
Step 6: Produce report
The final step is to present the results of the thematic analysis. This usually involves writing up each theme with supporting quotes from the data. The write-up should explain how each theme relates to the overall research question and highlight differences or patterns across participants.
Depending on the study, the report may also include visual models, comparisons across groups, or links to theoretical frameworks. The goal is to present the analysis in a way that makes the findings clear, grounded in the data, and useful for others.
This step may also include reflections on the researcher’s role, limitations of the analysis, and directions for further inquiry. By this stage, the thematic structure should be well-supported and clearly communicated to the intended audience.
How can NVivo AI Cloud help with interview data analysis?
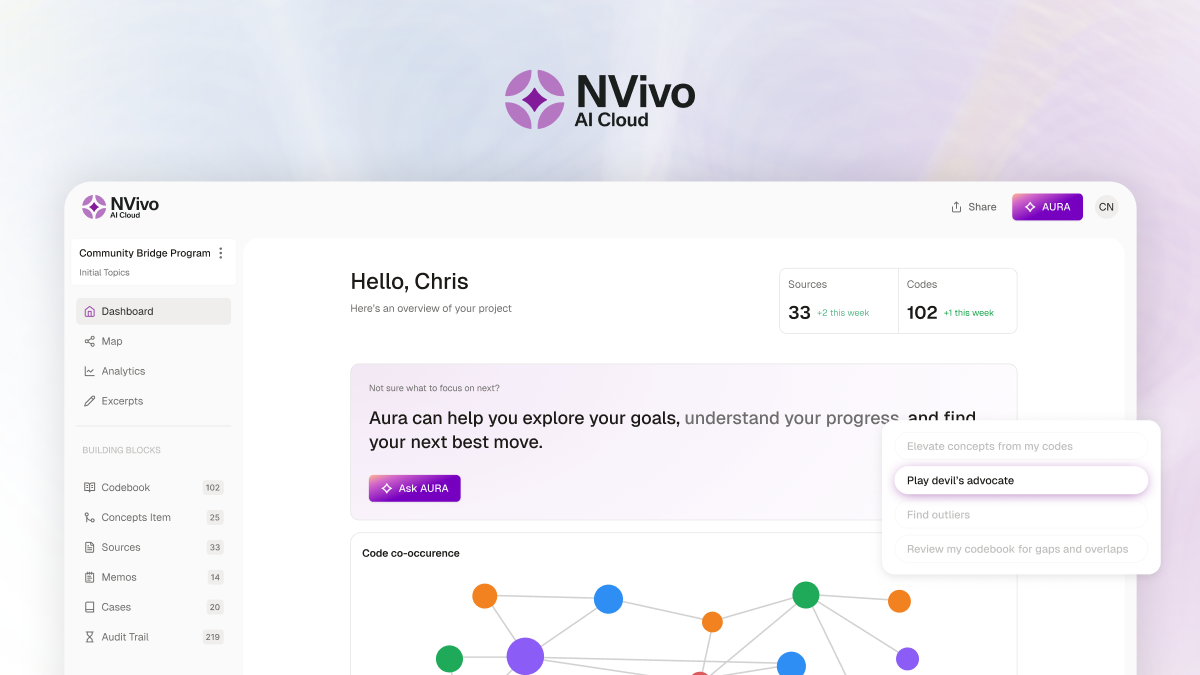
NVivo AI Cloud QDA software supports each stage of thematic analysis, helping researchers organize, code, and interpret interview data. It also offers tools to streamline transcription, structure or code open-ended responses, and ensure consistency across large projects—making the analysis process more efficient and manageable. Projects can be shared with a team, and the platform provides visual tools to support interpretation.
NVivo helps with interview data analysis by:
- Transcribing interview recordings
- Grouping the responses to each question
- Finding and cataloguing themes to make sense of the data
- Identifying connections between themes and moving toward analytical insight
- Making comparisons between participants
- Staying organized and focused on your research design
Transcribe interview recordings
NVivo AI Cloud lets you upload audio or video directly and transcribe it right in the platform—choose the spoken language, transcribe, then review and edit the transcript (including fixing speaker labels) before it becomes a source you code like any other.
The media player sits alongside the transcript so you can verify accuracy against the recording as you go, and every excerpt you code anchors to a time range in the recording rather than a position on the page—so correcting a transcript later doesn't lose your coding. Transcripts created outside the platform can also be imported directly
Group the responses to each question
NVivo AI Cloud can auto-identify cases and variables in one step: AURA reads an interview, focus group, or meeting transcript and identifies each speaker's turns, building a case per participant automatically—interviewers are kept separate under a Moderator role so their turns don't skew the analysis.
This groups each participant's responses together from the start, giving you a clean starting point for the case and variable comparisons covered later in this article, without manually tagging who said what.
Finding and cataloguing themes to make sense of the data
In NVivo AI Cloud, AURA identifies topics across your dataset with the supporting evidence attached, then auto-codes against the topics you confirm—every AI-suggested code still requires your approval before it joins the codebook.
Codes live in a hierarchical codebook, and an excerpt can carry more than one code as your reading sharpens. Memos link to their source excerpts in both directions, so you can explain a coding decision or record a reflection and trace it straight back to the passage that prompted it. The codebook shows how often each code has been applied, though frequency isn't the main indicator of relevance in thematic analysis.
Identifying connections between themes and move toward analytical insight
NVivo AI Cloud generates Code × Variable and Code × Code co-occurrence matrices automatically, so you can see how themes intersect with participant attributes or with each other without building a separate query.
Its interactive topic map shows codes as circles sized by frequency, with lines connecting where they co-occur—a fast way to spot which themes cluster together or which stand apart, and where the coding structure might have gaps.
Making comparisons between participants
NVivo AI Cloud auto-identifies case variables like role or location for you to confirm, edit, or delete, so you can filter and compare subgroups without manually building each attribute by hand.
Its Code × Variable matrix compares how themes appear across cases automatically—for example, whether a particular concern shows up more often in one demographic group than another—and it supports intra-case comparisons too, so you can track how one participant's perspective shifts across a longitudinal study.
Staying organized and focused on your research design
NVivo AI Cloud keeps every write action—a new code, a memo, a case—as a proposal you approve, never an automatic change. Its full audit trail, with AI-prompt inspection and AI/human attribution, records exactly who—or what—made each analytic decision, and the whole trail exports for a reviewer or committee.
A single dashboard shows what's coded most and where to dig deeper next, so you can stay oriented in a large project without losing sight of your original research design.
Additional resources related to this topic
To learn more about qualitative research, visit our article, "What is Qualitative Research?"
Explore our in-depth guide to learn more about qualitative data analysis.
Check out this article about tips for effective qualitative interviews.
Turn your interview data into insights with NVivo AI Cloud
Ready to work more efficiently with all the interview data in your research project? NVivo AI Cloud pairs AI-suggested topics and a fully auditable coding trail with the same qualitative research methodology researchers have trusted for over 30 years, to help you code, compare, and visualize your analysis—all in one place.
*(Scopus Database, 2010-2023)

How can we help you? Contact us.