











Key takeaways
The central question in qualitative research has shifted from whether AI can support analysis to who trusts its answers and who is accountable when it’s wrong. Adoption now depends on credibility, not capability: mature research teams use AI for pattern detection while keeping interpretation with the researcher. The most useful shift in good practice is moving from a human “in the loop” to a researcher “in the lead,” directing interpretation, documenting every decision, and testing AI outputs as rigorously as your own work.
Artificial intelligence (AI) has been around for decades, but the launch of ChatGPT in late 2022 marked a seismic shift in qualitative research. With its intuitive interface and freely available version, ChatGPT became widely accessible—lowering the barrier to entry and sparking experimentation in the research community.
This ease of access encouraged researchers to explore how AI could support qualitative work. At the same time, it raised concerns: misuse, ethical questions about how these tools are trained and how they handle uploaded content, and ongoing debates around reliability and trust.
Since then, the central question has changed. Researchers are no longer asking only whether AI can support qualitative analysis, but who trusts the answer, under what conditions, and who is accountable when it’s wrong. This update traces that shift from capability to credibility, and looks ahead to the disclosure, governance, and language choices that will shape what comes next in 2027.
It is worth distinguishing the terms. AI is the broad field of systems designed to perform tasks associated with human intelligence. Machine learning (ML) is a branch of AI in which systems learn patterns from data. GenAI uses learned patterns to generate new content, including text, images and audio. These are related, but not interchangeable, approaches (Kühl et al., 2020; Sengar et al., 2024).
The relationship between artificial intelligence, machine learning, and generative AI, with examples relevant to qualitative research.
My perspective throughout is interpretivist. I do not regard GenAI as an objective coder, or as a substitute for the researcher’s understanding of context. At its most useful, it is a dialogic partner: a way of asking new questions of the data, testing possible interpretations and challenging our assumptions. The researcher must remain in control of what is accepted, rejected, and ultimately claimed as a finding.

The changing landscape
Model capability has advanced rapidly and costs have fallen. Stanford’s 2026 AI Index reported that “AI capability is outpacing the benchmarks designed to measure it, and surpassing human-level performance.” The cost of querying a model with GPT-3.5-level benchmark performance declined from $20 per million tokens in November 2022 to $0.07 by October 2024.
This growth is accompanied by sheer volume: AI research outputs have exploded (three-fold growth since 2013) and model training demands keep rising. Qualitative scholars thus face both more powerful tools and new sustainability challenges ( Stanford HAI, 2025). For qualitative researchers, this “landscape” snapshot means we’re operating amid ever-more capable tools—from text analyzers to multimedia content generators—but also facing new challenges of keeping research practices sustainable and ethically sound in the face of AI’s rapid expansion.
A trend that complicates the efficiency narrative is the re-emerging performance gap between proprietary and open models. By March 2026, top closed models led open alternatives by 3.3 percentage points—up from 0.5% parity in August 2024. For researchers choosing privacy-critical or offline deployment, this represents a real capability constraint (Stanford HAI, 2025, 2026)
Yet capability and cost are only half the story: adoption now hinges on user trust and institutional willingness to rely on AI.
According to Lumivero’s 2026 “State of AI in Qualitative and Mixed Methods Research” report, 57% of researchers already use AI regularly or occasionally, yet 87% are concerned about accuracy and hallucination risk.
2026 has been defined by the gap between what AI can do and what researchers and consumers are willing to let it do. Among qualitative research leaders at mature organizations—Visa, Adobe, DSM-Firmenich, and Aylo—a pattern is emerging. These practitioners are neither rejecting AI nor adopting it wholesale. Instead, they are operating with deliberate discipline: using AI for pattern detection and hypothesis generation while validating findings through human research methods; embedding insights into decision-making forums rather than delivering isolated reports; tracking impact beyond delivery; and ruthlessly filtering new tools against a single question—will this preserve the quality and reliability of the work?
The consensus is stark: AI is augmentation, not replacement. The human piece always needs to touch it. What distinguishes mature organizations is not whether they use AI, but how intentionally they integrate it—and how accountable they remain for its application. The same pattern shows up in Lumivero’s survey data: 61% of surveyed researchers manually review AI’s output against source data themselves. In this framing, the gap between consumer hesitation and organizational adoption isn’t a problem to solve; it’s a feature of responsible practice (Merlien Institute, 2026).
Use of generative AI in academic research has also grown. In a systematic review of 189 papers on large language models in survey research, Buskirk et al. (2025) found a sharp rise in publications from 2022 to 2024. Applications ranged from question design and interviewing to data processing and synthetic respondents. What is more difficult to establish is whether greater speed produces better research. A plausible answer is not necessarily a valid one.
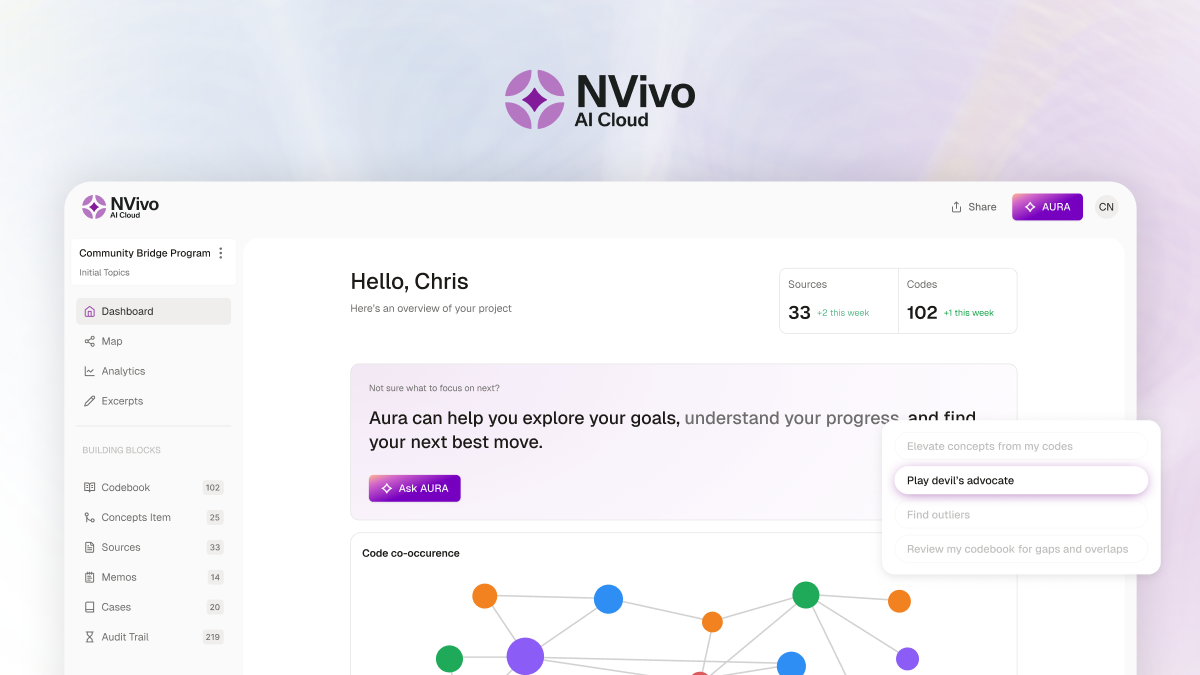
Qualitative data analysis software is evolving too. Alongside AI-assisted features in established desktop products, ATLAS.ti introduced an MCP server in 2026 that connects compatible AI assistants to a project. NVivo AI Cloud, launched in September 2026, takes a different route as an AI-native environment in which the researcher provides the context and research questions and the AI suggests actions linked to the context and sources—always requiring researcher approval (ATLAS.ti, 2026; Lumivero, 2026).
These developments put an important design question at the center of the discussion: can researchers see what AI has done, challenge it, and trace any proposed finding back to the evidence?
From coding to a dialogue with the data
Christou (2023) was among the early scholars to argue that AI should not be treated as a source of ready-made findings. His practical emphasis was on checking outputs, recognizing bias, and maintaining the researcher’s intellectual contribution. Those remain sound principles, although the tools with which researchers work are changing quickly.
The early academic literature demonstrated that GenAI could help with descriptive tasks, but also exposed its limitations. In a grounded theory study, Sinha et al. (2024) found that GPT-4 could contribute to generating and refining codes while researchers remained responsible for assessing its suggestions. Morgan (2023) similarly showed how ChatGPT could identify relatively straightforward themes, without establishing that it understood the deeper meanings carried by the data.
Concrete examples illustrate different entry points. Friese (2025a) outlines five stages: beginning with AI-generated summaries for familiarization, scaffolding analysis with researcher-designed questions, engaging in focused dialogue (typically 4-6 interviews), synthesizing insights, and testing theoretical hypotheses. Morgan (2025) proposes an alternative sequence: beginning with broad questions, moving to focused queries, then examining supporting data—reversing the traditional line-by-line coding step. Hayes (2025) documents a hybrid: iterative dialogue with GPT-4 and Claude to deepen interpretive insights while cautiously evaluating outputs. These are not identical methods, but they share a common move: treating coding as a conversation rather than categorization.
The possibilities extend beyond conventional coding. Stanford’s LLoOM project, for example, supports human–AI collaboration in identifying higher-level concepts across unstructured text (Lam et al., 2024). Such approaches may change the questions researchers can ask, not merely the speed at which they undertake existing tasks. Yet they still require close engagement with original material. A theme extracted without its setting, tensions, and exceptions is at best a starting point.
These approaches also change the demands on the researcher. Rather than treating the production of a codebook as evidence of analytical progress, we need to record why we pursued a particular question, which prompts helped us explore it and where the data resisted the interpretation being offered. A reflexive journal or analytic memo can capture the reasons for adopting or rejecting a suggested theme. What matters is not whether AI generated an idea, but how that idea was examined in the context of the research questions, theoretical commitments, and participants' accounts.
The methodological debate
Not everyone accepts that GenAI belongs in reflexive qualitative work. In an open letter subsequently published in Qualitative Inquiry, Jowsey, Braun, Clarke, Lupton, Fine and fellow signatories reject its use in ‘Big Q’ approaches, including reflexive thematic analysis. Their argument is methodological as well as ethical: Their case rested on three grounds: that GenAI, as "simulated intelligence," is incapable of genuine meaning-making; that reflexive qualitative work must remain an exclusively human practice in every phase, including initial coding; and that the environmental and labor harms tied to AI infrastructure—data-center resource use, and the psychological toll on data-labeling workers in the Global South—make its use ethically untenable regardless of methodological merit (Jowsey et al., 2025)..
Friese’s response argues that this position underestimates how researchers can use AI without handing over interpretive authority. For her, AI provides scaffolding for thought rather than an independent interpretation of experience. Drawing on established traditions of distributed cognition and socio-material practice (Hutchins, 1995; Barad, 2007; Orlikowski, 2007), she argues that reflexive meaning-making has never occurred in total isolation from tools, memos, or peer dialogue, and that AI-assisted scaffolding is a difference of degree rather than kind. On the environmental and labor concerns, she doesn't dispute the underlying harms, but argues that individual researcher abstinence is a largely symbolic response to a systemic, industry-level problem, and that advocacy for regulation, renewable-hosted models, and disclosure of energy and water use does more good than blanket refusal (Friese, 2025b).
A subsequent response co-authored by Friese, Nguyen-Trung, Powell and Morgan (2026) argues for space between blanket rejection and uncritical enthusiasm. This is a real methodological disagreement, not one that can be resolved by reporting better benchmark scores.
I share the insistence that interpretation belongs to the researcher. But I also think we need to investigate how AI changes the work of analysis in practice. Does it encourage us to notice perspectives we might otherwise miss, or does it draw us towards familiar explanations? Does it support immersion in the data or encourage premature closure? These are research questions, not just technical ones.
The debate is sometimes described as a simple division between people who welcome innovation and those who resist it. That is unhelpful. The objections concern the nature of knowledge in qualitative research and the conditions in which AI is developed and used; the response concerns whether forms of human–AI dialogue can be compatible with those commitments. Different qualitative traditions will reach different judgments. It would be a mistake to assume that one approach to AI should apply equally to a descriptive content analysis, an ethnography, and reflexive thematic analysis.
Industry research and AI-moderated interviewing
In market, social, and user-experience research, GenAI is moving beyond analysis of existing text into research design, interviewing, and reporting. Platforms now offer draft interview guides, AI-moderated conversations, rapid synthesis, and synthetic respondents. These uses require different judgments. An AI-generated guide can be revised before fieldwork; an AI interviewer is actively shaping the data being collected; a synthetic respondent is not a substitute for a person’s lived account.
Industry presentations at Qual360 2026 pointed to both opportunity and friction. Speakers described rapid AI-moderated studies, but also participant drop-off, the need to spot-check transcripts and the risk that automated probing misses emotion or context. Institutional approval processes may be an obstacle even when tools are technically capable. These conference examples are useful illustrations, although the underlying study reports should be obtained before quoting performance figures as established findings.
This raises a distinction that runs through academic and commercial work alike. AI may detect repeated patterns in thousands of responses, but it cannot by itself determine why an account matters in a particular social setting. The attraction of scale should not obscure what can be lost: the unexpected turn in an interview, the hesitation, or the contradiction that calls the researcher's assumptions into question.
The most concrete challenge to the "AI enables limitless scale" narrative came from Sago's Chief Strategy Officer, Melanie Cartwright, who tested an AI moderator across 2,400 surveys. The results complicate the efficiency story. Cartwright found meaningful modality effects: video and audio moderation showed 21% participant drop-off, compared with lower attrition for text. Text sessions produced the sparsest responses; audio generated roughly double the word count. Turnaround was genuinely fast—two weeks from kickoff to report—but only because manual transcript spot-checks and fraud-detection adjustments were built into the workflow from the start. The fraud-detection system, in particular, had to be retuned after it over-removed legitimate responses.
The implication is stark: adding an AI moderator does not remove human decision-making from the research process. It relocates those decisions. Rather than occurring during fieldwork (recruitment, guide design, live probing), they now occur in preparation and quality review.
Cartwright also named where AI-moderated research breaks down, and her framework is more useful than generic cautions about bias. Mirrors, not lenses—the system reflects respondents' own framing back at them rather than offering a new way of seeing. Loss of context. Bias amplification. Emotional meaning stripped away. Lack of awareness of its own errors. Lack of empathy. Lack of research experience. These are not failures of current AI models; they are structural properties of the medium. They are also testable claims researchers can build checks around.
Her accounting of AI's genuine strengths is equally worth naming: rapid pattern detection across thousands of responses, speed to core signal, consistency in probing, video content compilation, and on the respondent side, flexibility and lower social anxiety. The distinction matters. Cartwright's framework makes clear what AI-moderated research is built for and what it is not—and that distinction is more important than simply knowing the technology works (Cartwright, 2026).
By 2026, the industry conversation has shifted decisively on this point. Last year, the question was whether AI-moderated interviews were viable at all. This year, the question is which specific human oversight practices make them trustworthy. That shift—from capability to governance—is itself the story.
Trust, institutional policy, and disclosure
Policy has not always kept pace with practice. In a study of guidelines at 50 leading U.S. universities, An et al. (2025) found that 94% had guidance aimed at faculty, but fewer than 20% had guidance specifically for researchers. Ganguly et al. (2025), examining 30 U.S. research-intensive institutions, found that researchers were often expected to navigate changing rules, disclosure obligations, and data-protection requirements themselves. Publishers likewise expect authors to take responsibility for AI-assisted work, although disclosure requirements differ (Ganjavi et al., 2024).
The policy gap has concrete costs. Brian Laverty (2026) of Warner Bros. Discovery (WBD) and observers at Marriott International both reported provisioning processes taking months to clear legal and IT review—months when the technology was ready, but institutional approval frameworks were not. WBD's resolution is instructive: AI is kept visibly labeled, used for specific, debated purposes (motion induction in screeners, logic checks, synthetic respondents for internal training), with its use to supplement rather than replace small human samples explicitly discussed rather than assumed.
For me, the communication problem is as important as the policy gap. In interviews I conducted in 2026 on how researchers talk about AI, I found that they were often having four rather different conversations: with respondents about consent and privacy; with clients about quality and trade-offs; with institutions and colleagues about security and permissible use; and with other researchers about methodological credibility and disclosure.
An epistemic authority framework (Bartsch et al., 2024) illuminates why institutional confusion persists. When legitimacy is socially claimed inconsistently, the same objectively identical system ends up over-trusted or under-trusted depending on how it's named. As one of my interviewees noted, 'Copilot isn't a dirty word, but ChatGPT is'—the same underlying cloud infrastructure, trusted under one name and blocked under another. Another described an institution approving an enterprise ChatGPT service while questioning an AI feature using a similar enterprise arrangement. These interview accounts are illustrations of perceived inconsistency, not a technical audit of the systems concerned. They nevertheless show how legitimacy is negotiated through language as well as evidence (di Gregorio, 2026).
Disclosure is becoming more concrete. AAPOR’s 2026 report proposes both minimum and enhanced AI disclosures for survey research, including enough detail to understand the tool’s role, assess limitations and support reproducibility (AAPOR, 2026). A useful record should identify the system and version where possible, the dates and purpose of use, the data it could access, what the researcher checked and what was changed or rejected. Disclosure alone does not make an analysis sound, but it allows others to evaluate how the work was done.
The four audiences require different explanations, not different standards of honesty. A respondent needs to know what happens to their words. A client needs to understand what was automated and whether that affects confidence in the findings. An institutional reviewer needs a clear account of access, retention, and accountability. Research peers need sufficient methodological detail to assess the analysis. Describing AI merely as an 'assistant' can hide these differences. Conversely, naming a well-known brand without explaining the system's role can create an impression of familiarity that is not the same as informed trust.
Ethics, limitations, and researcher responsibility
Qualitative material can contain highly sensitive accounts. De-identifying transcripts may be necessary, but it is not sufficient: researchers must also understand where data are processed, whether they are retained or used for training, what contractual safeguards apply and whether consent covers AI processing. Consent to recording is not automatically consent to analysis by a third-party AI system. These decisions should be made before data are uploaded, not after an output has proved useful.
There are also risks to the analysis itself. GenAI can produce a fluent but invented quotation, blend several participants’ accounts or privilege the most common interpretation at the expense of an unusual but important one. It may reproduce assumptions embedded in training data and present them with unwarranted confidence. As Morgan (2023) cautioned, descriptive patterns are not the same as latent meanings. The practical test is whether an AI-assisted claim can be followed back to the evidence and examined against alternatives.
Melanie Cartwright of Sago (2026) offered the sharpest single articulation of where AI-moderated interviewing fails. Her framework distinguishes mirrors from lenses—reflecting respondents' framing back rather than offering new perspective—and identifies specific breakdowns: loss of context, bias amplification, emotional meaning stripped away, lack of awareness of its own errors, and lack of empathy or research expertise.
Environmental resources and the conditions of work behind AI systems also belong in a responsible assessment, as the debate between Jowsey and colleagues and their respondents makes clear. These costs should neither be ignored nor treated as a question that software design alone can resolve. Researchers need an explicit account of the benefit they expect, the risks involved, and the alternatives available (Resnik & Hosseini, 2025).
An interviewee in my 2026 study described realizing, after the fact, that her participant information covered recording but was less clear about AI use. This is precisely the kind of gap that ordinary procedural language can conceal. Researchers may think they have addressed confidentiality because they are using an approved enterprise system, while participants are asking a different question: who or what will read my account, and for what purpose? Trust needs to be earned at both levels.
What good practice looks like
The most useful shift in 2026 is from saying ‘keep a human in the loop’ to specifying what that person actually does—keeping the human in the lead. My starting point would be four practices:
- Direct interpretation. You examine the data, generate codes, and develop interpretations. Use AI to surface patterns or propose alternatives to your thinking—but you decide what the codes mean, which interpretations hold, and which evidence matters. Maintain clear attribution: what you read directly versus what AI surfaced.
- Author the analysis. You own every analytical decision. Document what you tried, what you accepted, what you rejected, and your reasoning. The audit trail is the analysis—it shows how you worked through the problem, not how AI assisted you.
- Scope AI deliberately. Before you start, decide where AI augments your thinking (pattern recognition, alternative framings, speed) and where human judgment is nonnegotiable (coding sensitive data, interpreting context-dependent meaning, decisions affecting participants). Revisit these boundaries as the analysis evolves.
- Interrogate rigorously. Test your own work and AI proposals equally hard. Try competing prompts, hunt for disconfirming evidence, compare AI-assisted coding with your close reading. This isn’t quality control—it’s how you strengthen your analysis.
These practices do more than prevent errors. They preserve reflexivity by requiring researchers to articulate their own assumptions and decisions. The aim is not to make AI appear objective; it is to make the analytical process more open to scrutiny.
It can also help to distinguish a researcher 'in the loop' from a researcher ‘in the lead’. In the first case, the researcher evaluates particular outputs, accepts or rejects suggestions, and may revise them. In the second, the researcher is responsible for how the overall process is governed: which tasks are delegated, how quality is sampled and when a workflow should be stopped.
These are different forms of oversight. Neither is adequate if the researcher cannot inspect the evidence behind a confident answer. An audit trail should record decisions without becoming a substitute for engagement with the data.
Conclusion
A year ago, this article closed by noting that GenAI had moved from siloed labs into mainstream qualitative research, and that its value depended on researchers remaining transparent, critical, and reflexive. That conclusion still holds—but 2026 has sharpened what "transparent" actually requires in practice. It is not enough to disclose that AI was used; the specific vocabulary chosen to describe that use—assistant, thinking partner, supporting tool, enterprise system, brand name—carries its own claim to authority, and audiences respond to that claim differently depending on who they are and what they already trust. This is a legitimacy problem, and legitimacy is negotiated in language, audience by audience, disclosure by disclosure. Talk shapes authority. So talking carefully about AI is now part of the qualitative method itself, not a footnote to it.
The clearest single instance of this dynamic in 2025–2026 wasn't a conference panel but an open letter: 416 qualitative researchers publicly rejecting GenAI for reflexive analysis outright, met within two weeks by a public rebuttal arguing the rejection itself rested on a mischaracterization of how the technology is actually used in practice. Both sides were, in their own way, making a claim about who has the standing to say AI's use is legitimate—which is exactly the argument this piece has been tracing all along.
For respondents, that means naming AI's role explicitly in consent, even inside environments that feel low-risk. For clients, it means leading with trade-offs rather than capability claims. For institutions, it means recognizing that the vocabulary problem is bigger than the technology problem, and that brand confusion is actively driving policy fragmentation. For research peers, it means disclosing prompts, bounding AI's interpretive role, and reserving final authority for the researcher's own judgment.
As one of my 2026 interviewees put it plainly: be honest, because others are already using AI more than they're saying they are. That, more than any benchmark score or adoption statistic, is the state of AI in qualitative research in 2026.
Dig deeper into Lumivero’s survey data
Discover key findings on how researchers are adopting, trusting, and governing AI in their qualitative and mixed methods work. Download Lumivero’s “The State of AI in Qualitative and Mixed Methods Research” today.
Download report →
Silvana di Gregorio, PhD
Head of Qualitative Research and Product Research Director, Lumivero
Silvana is a sociologist and a former academic. She has been training, consulting, and publishing about qualitative data analysis software since 1995. She is author of "Voice to Text: Automating Transcription,” “Using Web 2.0 Tools for Qualitative Analysis,” and co-author with Judith Davidson of “Qualitative Research Design for Software Users” and “Qualitative Research and Technology: In the Midst of a Revolution,” and co-author with Linda Gilbert and Kristi Jackson of “Tools for Qualitative Analysis.” She is part of the product marketing team at Lumivero.
References
American Association for Public Opinion Research (AAPOR). (2026). Responsible AI integration in survey research.
https://aapor.org/wp-content/uploads/2026/05/Responsible-AI-Integration-In-Survey-Research.pdf
An, Y., Yu, J. H., & James, S. (2025). Investigating the higher education institutions’ guidelines and policies regarding the use of generative AI in teaching, learning, research, and administration. International Journal of Educational Technology in Higher Education, 22, Article 10. https://doi.org/10.1186/s41239-025-00507-3
ATLAS.ti. (2026). ATLAS.ti update history: Version 26.1.0—MCP Server. https://atlasti.com/updates
Cartwright, M. (2026). The human imperative: building trust in an ai-driven insights ecosystem, presentation at Qual360 NA, 14 May 2026, Washington, DC.
Christou, P. (2023). How to use artificial intelligence (AI) as a resource, methodological and analysis tool in qualitative research? The Qualitative Report, 28(7), 1968–1980. https://doi.org/10.46743/2160-3715/2023.6406
Barad, K. (2007). Meeting the universe halfway: Quantum physics and the entanglement of matter and meaning. Duke University Press. https://doi.org/10.1215/9780822388128
Bartsch, A., Neuberger, C., Stark, B., Karnowski, V., Maurer, M., & Pentzold, C., Quandt, T. , Quiring, Ol., Schemer, C. (2024). Epistemic authority in the digital public sphere. An integrative conceptual framework and research agenda. Communication Theory. 35. 37-50. https://doi.org/10.1093/ct/qtae020.
Buskirk, T. D., Keusch, F., von der Heyde, L., & Eck, A. (2025). More parameters than populations: A systematic review of large language models in survey research. Proceedings of COLM 2025. https://openreview.net/pdf?id=0Hxhwa56Yg
di Gregorio, S. (2026). How do we talk about AI in Qualitative Research? Mapping the language of credibility, transparency, and trust through the lens of epistemic authority. Paper presented at the AAPOR conference, 12-15 May 2026, Los Angeles.
Friese, S. (2025a). From Coding to Conversation: A New Methodological Framework for AI-Assisted Qualitative Analysis. SSRN. https://doi.org/10.2139/ssrn.5232579
Friese, S. (2025b). Response to “We reject the use of generative artificial intelligence for reflexive qualitative research.” SSRN. https://doi.org/10.2139/ssrn.5690262
Friese, S., Nguyen-Trung, K., Powell, S., & Morgan, D. (2026). Beyond binary positions: Making space for critical and reflexive GenAI integration in qualitative research. Qualitative Inquiry. https://doi.org/10.1177/10778004261429393
Ganguly, A., Johri, A., Ali, A., & McDonald, N. (2025). Generative artificial intelligence for academic research: Evidence from guidance issued for researchers by higher education institutions in the United States. AI and Ethics, 5, 3917–3933. https://doi.org/10.1007/s43681-025-00688-7
Ganjavi, C., Eppler, M. B., Pekcan, A., Biedermann, B., Abreu, A., Collins, G. S., Gill, I. S., & Cacciamani, G. E. (2024). Publishers’ and journals’ instructions to authors on use of generative artificial intelligence in academic and scientific publishing: Bibliometric analysis. BMJ, 384, e077192. https://doi.org/10.1136/bmj-2023-077192
Hayes, A. S. (2025). “Conversing” with qualitative data: Enhancing qualitative research through large language models (LLMs). International Journal of Qualitative Methods, 24. https://doi.org/10.1177/16094069251322346
Hutchins, E. (1995). Cognition in the wild. MIT Press. https://doi.org/10.7551/mitpress/1881.001.0001
Jowsey, T., Braun, V., Clarke, V., Lupton, D., & Fine, M. (2025). We reject the use of generative artificial intelligence for reflexive qualitative research. Qualitative Inquiry. https://doi.org/10.1177/10778004251401851
Kühl, N., Goutier, M., Hirt, R., & Satzger, G. (2020). Machine learning in artificial intelligence: Towards a common understanding. arXiv. https://doi.org/10.48550/arXiv.2004.04686
Lam, M. S., Teoh, J., Landay, J. A., Heer, J., & Bernstein, M. S. (2024). Concept induction: Analyzing unstructured text with high-level concepts using LLoOM. CHI 2024. https://doi.org/10.1145/3613904.3642830
Laverty, B. (2026). AI and Qual: Navigating risks and unlocking opportunities. Paper presented at Qual360 NA, 14 May 2026, Washington, DC.
Lumivero. (2026, September 28). Lumivero launches NVivo AI Cloud, powered by AURA. https://lumivero.com/resources/newsroom/nvivo-ai-cloud-launch/
Merlien Institute. (2026). Agentic AI in qualitative research: Visa at QUAL360 NA 2026. Merlien. Retrieved October 14, 2026, from https://merlien.com/agentic-ai-in-qualitative-research-visa-at-qual360/
Morgan, D. L. (2023). Exploring the use of artificial intelligence for qualitative data analysis: The case of ChatGPT. International Journal of Qualitative Methods, 22. https://doi.org/10.1177/16094069231211248
Morgan, D. L. (2025). Query-based analysis: A strategy for analyzing qualitative data using ChatGPT. Qualitative Health Research (published online 2025; 36[2–3], 206–217 in 2026). https://doi.org/10.1177/10497323251321712
Orlikowski, W. J. (2007). Sociomaterial practices: Exploring technology at work. Organization Studies, 28(9), 1435–1448. https://doi.org/10.1177/0170840607081138
Resnik, D. B., & Hosseini, M. (2025). The ethics of using artificial intelligence in scientific research: New guidance needed for a new tool. AI and Ethics, 5, 1499–1521. https://doi.org/10.1007/s43681-024-00493-8
Sengar, S. S., Hasan, A. B., Kumar, S., & Carroll, F. (2024). Generative artificial intelligence: A systematic review and applications. arXiv. https://doi.org/10.48550/arXiv.2405.11029
Sinha, R., Solola, I., Nguyen, H., Swanson, H., & Lawrence, L. (2024). The role of generative AI in qualitative research: GPT-4’s contributions to a grounded theory analysis. Symposium on Learning, Design and Technology, 17–25. https://doi.org/10.1145/3663433.3663456
Stanford Institute for Human-Centered Artificial Intelligence (HAI). (2025). The 2025 AI Index Report: Research and development. https://hai.stanford.edu/ai-index/2025-ai-index-report/research-and-development
Stanford Institute for Human-Centered Artificial Intelligence (HAI). (2026). The 2026 AI Index Report: Technical performance. https://hai.stanford.edu/ai-index/2026-ai-index-report/technical-performance